Your One Stop Bio Solutions
A weekend cohort, taught 100% live and hands-on from Python foundations to production-ready ML pipelines. Built for students, researchers, and professionals from any background — no prior coding required.
Direct interaction with mentors in every session. Ask questions in real-time with zero pre-recorded shortcuts.
Write, run, and debug real Python code from the very first hour. Reinforce concepts through guided coding exercises.
Work directly with authentic real-world datasets across practical domains to master data preprocessing, feature engineering, and predictive modeling from scratch.
Designed specifically as a gentle, structured on-ramp for students, professionals, and learners from all academic branches.
If you can open a spreadsheet, you can learn to build a model. This program is tailored to bridge the computational gap.
Undergraduate, postgraduate, and PhD scholars across engineering, sciences, commerce, and computer applications.
Professionals, analysts, and developers looking to upskill in Machine Learning, Python, and AI modeling.
Computer Science & IT students aiming to build production-grade, reproducible ML portfolio projects.
Mechanical, civil, electrical, electronics, chemical, and all engineering branches.
Statistics, mathematics, economics, physics, and chemistry graduates pursuing applied data science.
Academicians, postdocs, and researchers aiming to integrate machine learning and predictive modeling into projects.
Learners transitioning from theory to building structured, end-to-end reproducible machine learning code.
No prior coding or ML knowledge required — just curiosity, dedication, and consistency.
A step-by-step path from Python foundations to building, tuning, and tracking production-grade machine learning pipelines.
Variables, Data Types, Conditionals, Loops, & Custom Functions
NumPy array operations, vectorization, Pandas DataFrames & Series
Handling missing data, imputation methods, normalization, & feature scaling
Statistical data exploration, distribution analysis, and correlation insights
Preparing clean, structured, and validated datasets ready for ML modeling
Learn with labeled structured & numerical data to predict target outcomes
Find hidden structures and clustering patterns in unlabeled datasets
Predict continuous numerical values using Linear, Ridge, & Lasso regression
Predict discrete classes with Decision Trees, Random Forests, & SVMs
Group similar data points using K-Means and Hierarchical clustering
Train/Test splits, accuracy scores, bias-variance tradeoff, & overfitting checks
Organize code, data, models, and results for clean and scalable project repositories
Track revisions, manage commit trees, create branches, and collaborate on GitHub
Write clean, reusable, and maintainable Python code with modular functional design
Save and load trained models for production deployment using Joblib or Pickle
Track experiments, parameters, and loss metrics to make data-driven decisions
Create new features, binning transforms, and interaction terms to capture patterns
Reduce dimensionality and select highest-impact features via PCA & Importance
Evaluate model stability and generalization reliably using K-Fold cross-validation
Systematically search and find optimal parameters using GridSearchCV & RandomSearch
Evaluate models with Precision, Recall, F1-Score, and ROC-AUC curve comparisons
Gain hands-on proficiency with the modern computational toolchain used by data science and machine learning engineers worldwide.
Build portfolio-ready models using authentic real-world datasets from leading global data science and machine learning repositories:
Implement standard ML pipelines with verified high accuracy on real datasets.
Master data cleaning, scaling, imputation, and PCA on real-world datasets.
Build a structured, version-controlled GitHub repository to showcase in interviews.
Authenticated certificate signed by Biosyntiya Solutions, shareable on LinkedIn.
Early-bird cohort pricing with small batch size for personalized, focused learning. Select your track below.
UG / PG / PhD scholars & early researchers
Industry professionals, scientists & consultants
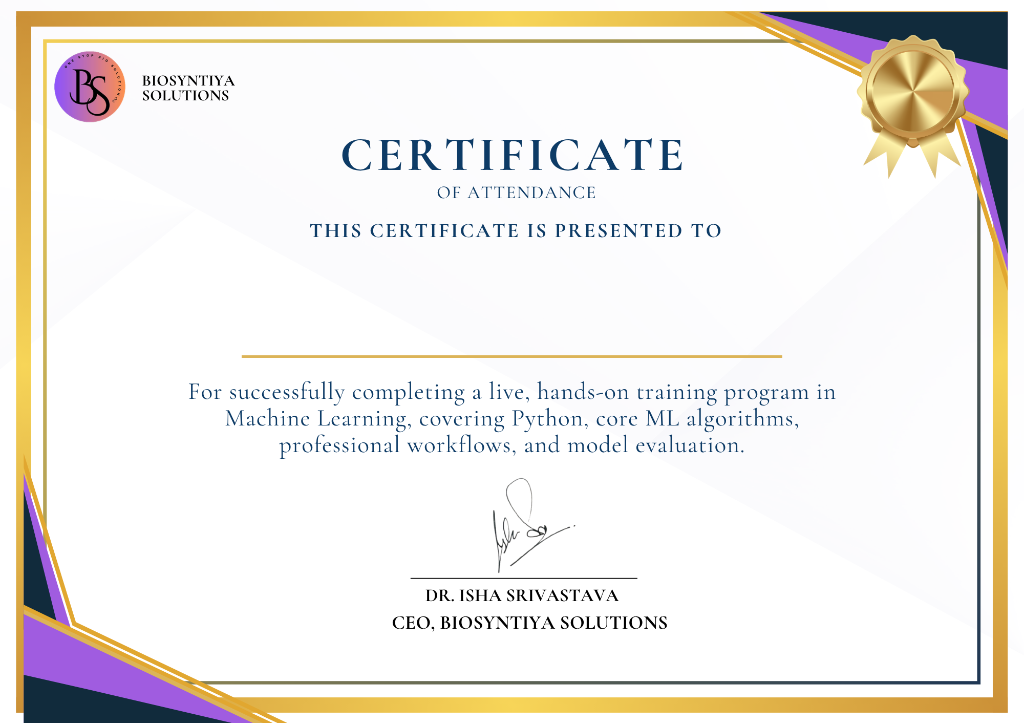
Strengthen your academic CV, research portfolios, and job applications with an authenticated certificate of completion documenting your hands-on proficiency in Python data pipelines, Scikit-Learn modeling, feature engineering, and predictive analytics.
Instant digital scan verification allows recruiters and university panels to validate your credential authenticity.
Signed by Dr. Isha Srivastava (CEO, Biosyntiya Solutions) with official Biosyntiya organizational seal.
Documents hands-on mastery of Python, Pandas, NumPy, Scikit-Learn pipelines, GridSearchCV, and ROC-AUC evaluation.
Add credential details directly to the Licenses & Certifications section of your LinkedIn profile.
Authentic feedback from researchers and students mentored by Biosyntiya Solutions.
"The live, small-batch format made all the difference. As a beginner with zero coding background, having the mentor explain code line by line was invaluable."
"The hands-on approach and direct guidance at Biosyntiya Solutions gave me the exact confidence I needed to apply ML models to complex real-world datasets."
"Extremely well structured. From Python data preprocessing to Git and Scikit-Learn pipelines, everything was practical and immediately applicable."
Join our next live weekend cohort. Conducted with a small batch size to ensure personalized mentorship, focused learning, and real project portfolios.